Traditionally, patents have been searched using complex boolean queries. The searcher wants to know if a complex idea exists in some of the 100+ million documents in the global patent data – it’s a use-case where control and precision are key. Boolean is the logical fit, and we have also added support for it in IPRally. Even then, working with the boolean can be laborious and painful, and our target has always been a more humane experience for patent professionals with our graph-based approach. Graph AI has been our main offering since 2018, and it keeps on moving fast forward. Following last year’s advancements with Graph Transformer 2.0, we have now reached a new milestone with the latest release of the deep learning model that powers our search. Thanks to the team's brilliant work, the quality of our search results has reached new heights.
Drastically Improved Search Quality
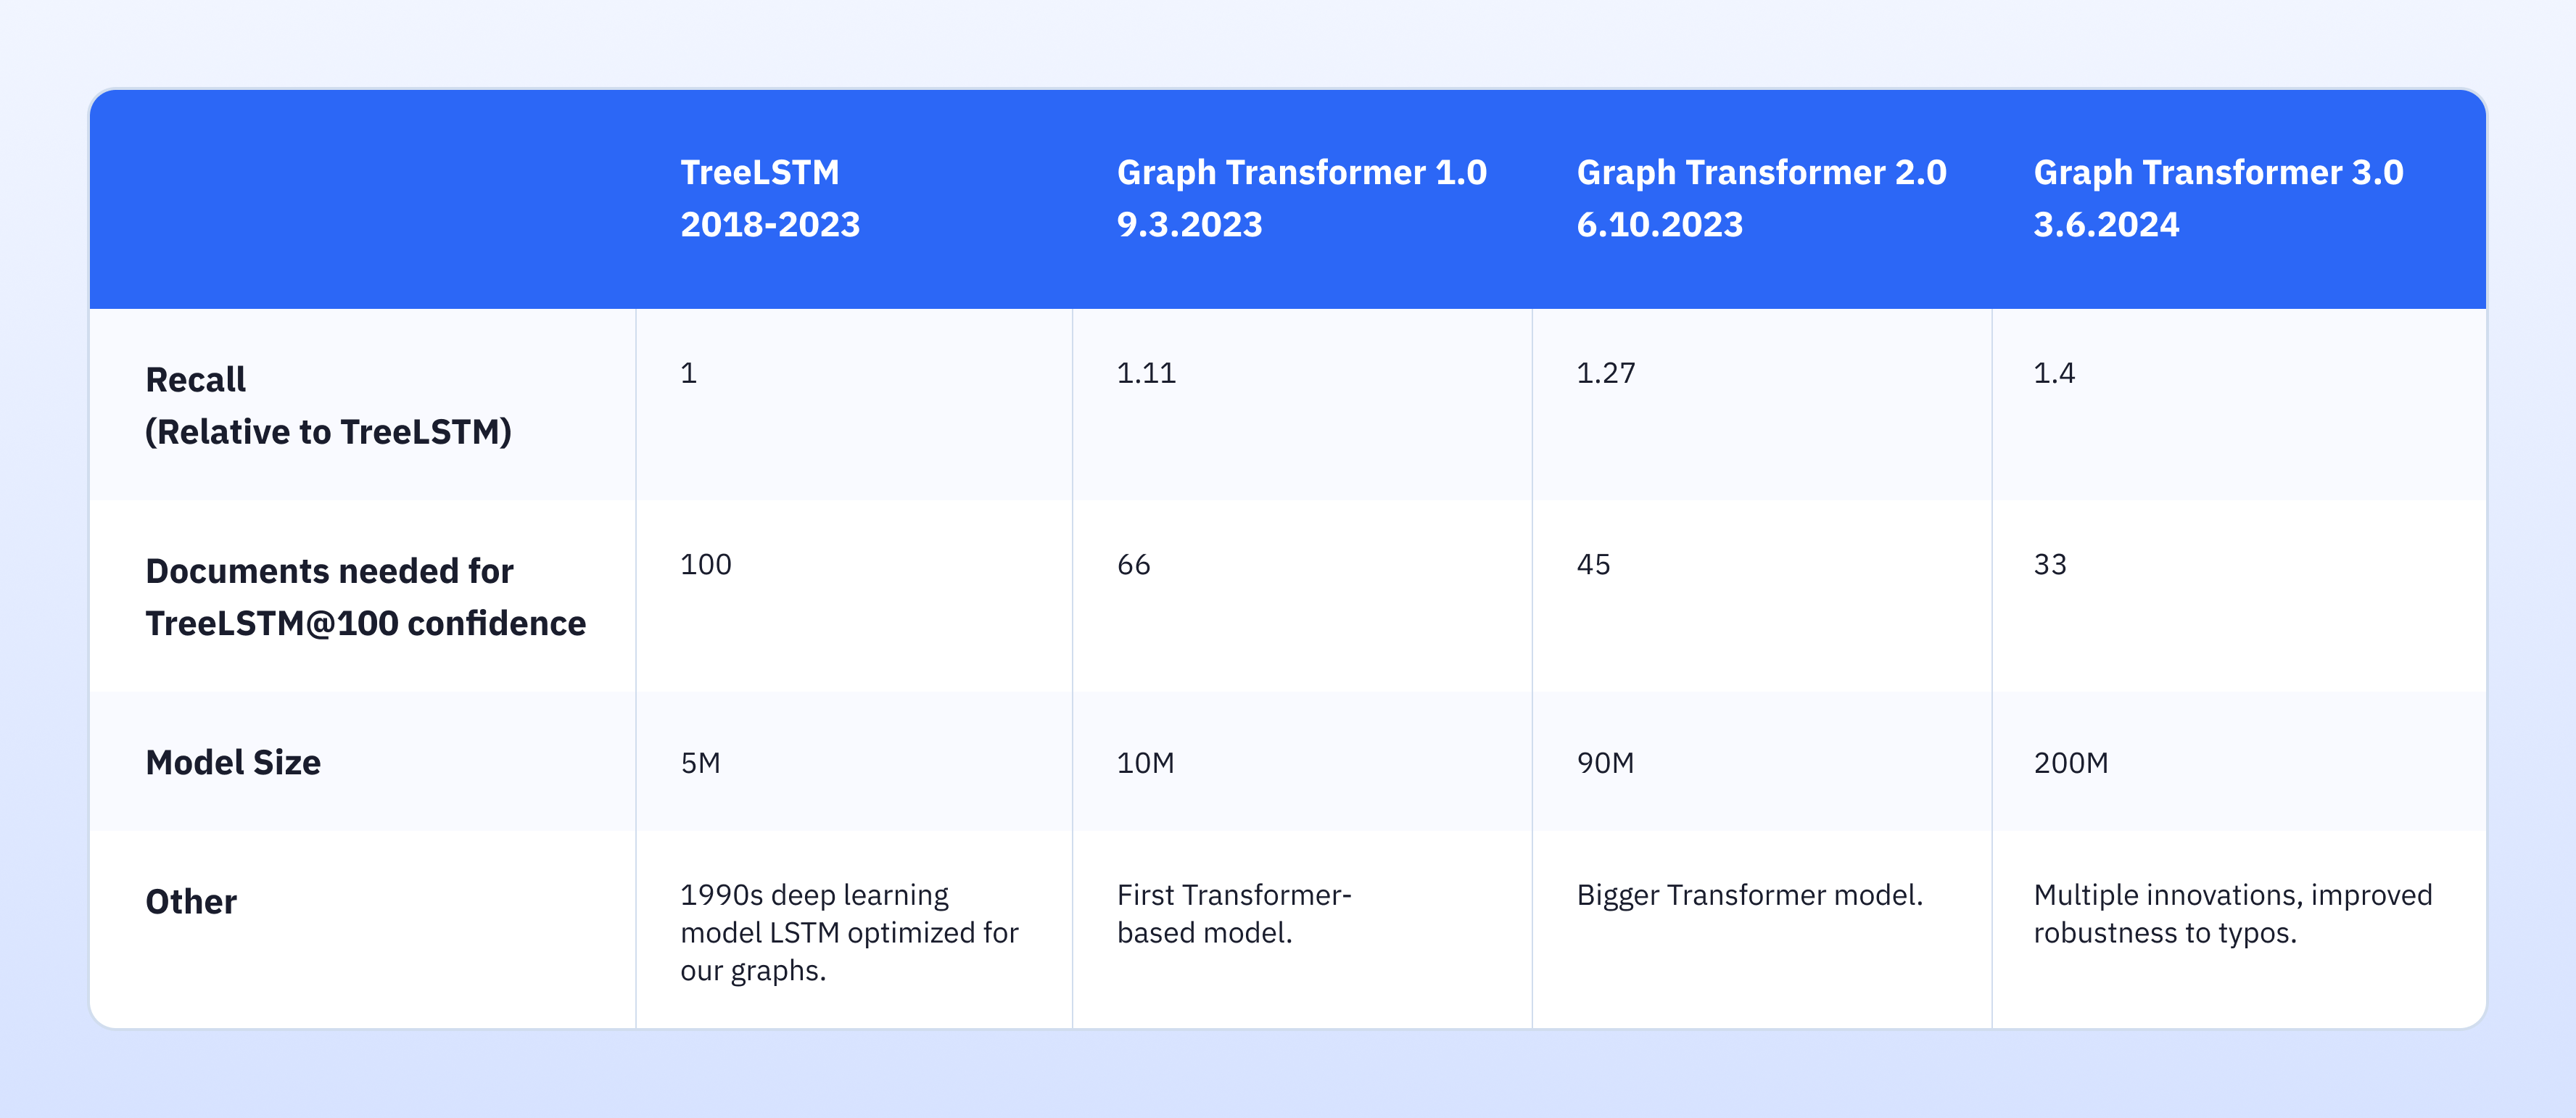
The new search model enhances the search result quality, boosting recall metrics by 10% across the board. This represents a major leap forward given the maturity of the previous model. A 10% improvement in an abstract metric may not fully capture the impact, but it's a difference you'll notice when you experience it firsthand. Further, we need to zoom a bit further out to grasp where the development is heading.
So, does this mean the end of the Boolean era? Perhaps not yet, but patent search is evolving rapidly. When Boolean search is hardly developing, it's hard not to view it as endangered in today's dynamic environment. With each iteration, AI continues to cover areas traditionally dominated by Boolean methods.
Splitting the Required Results
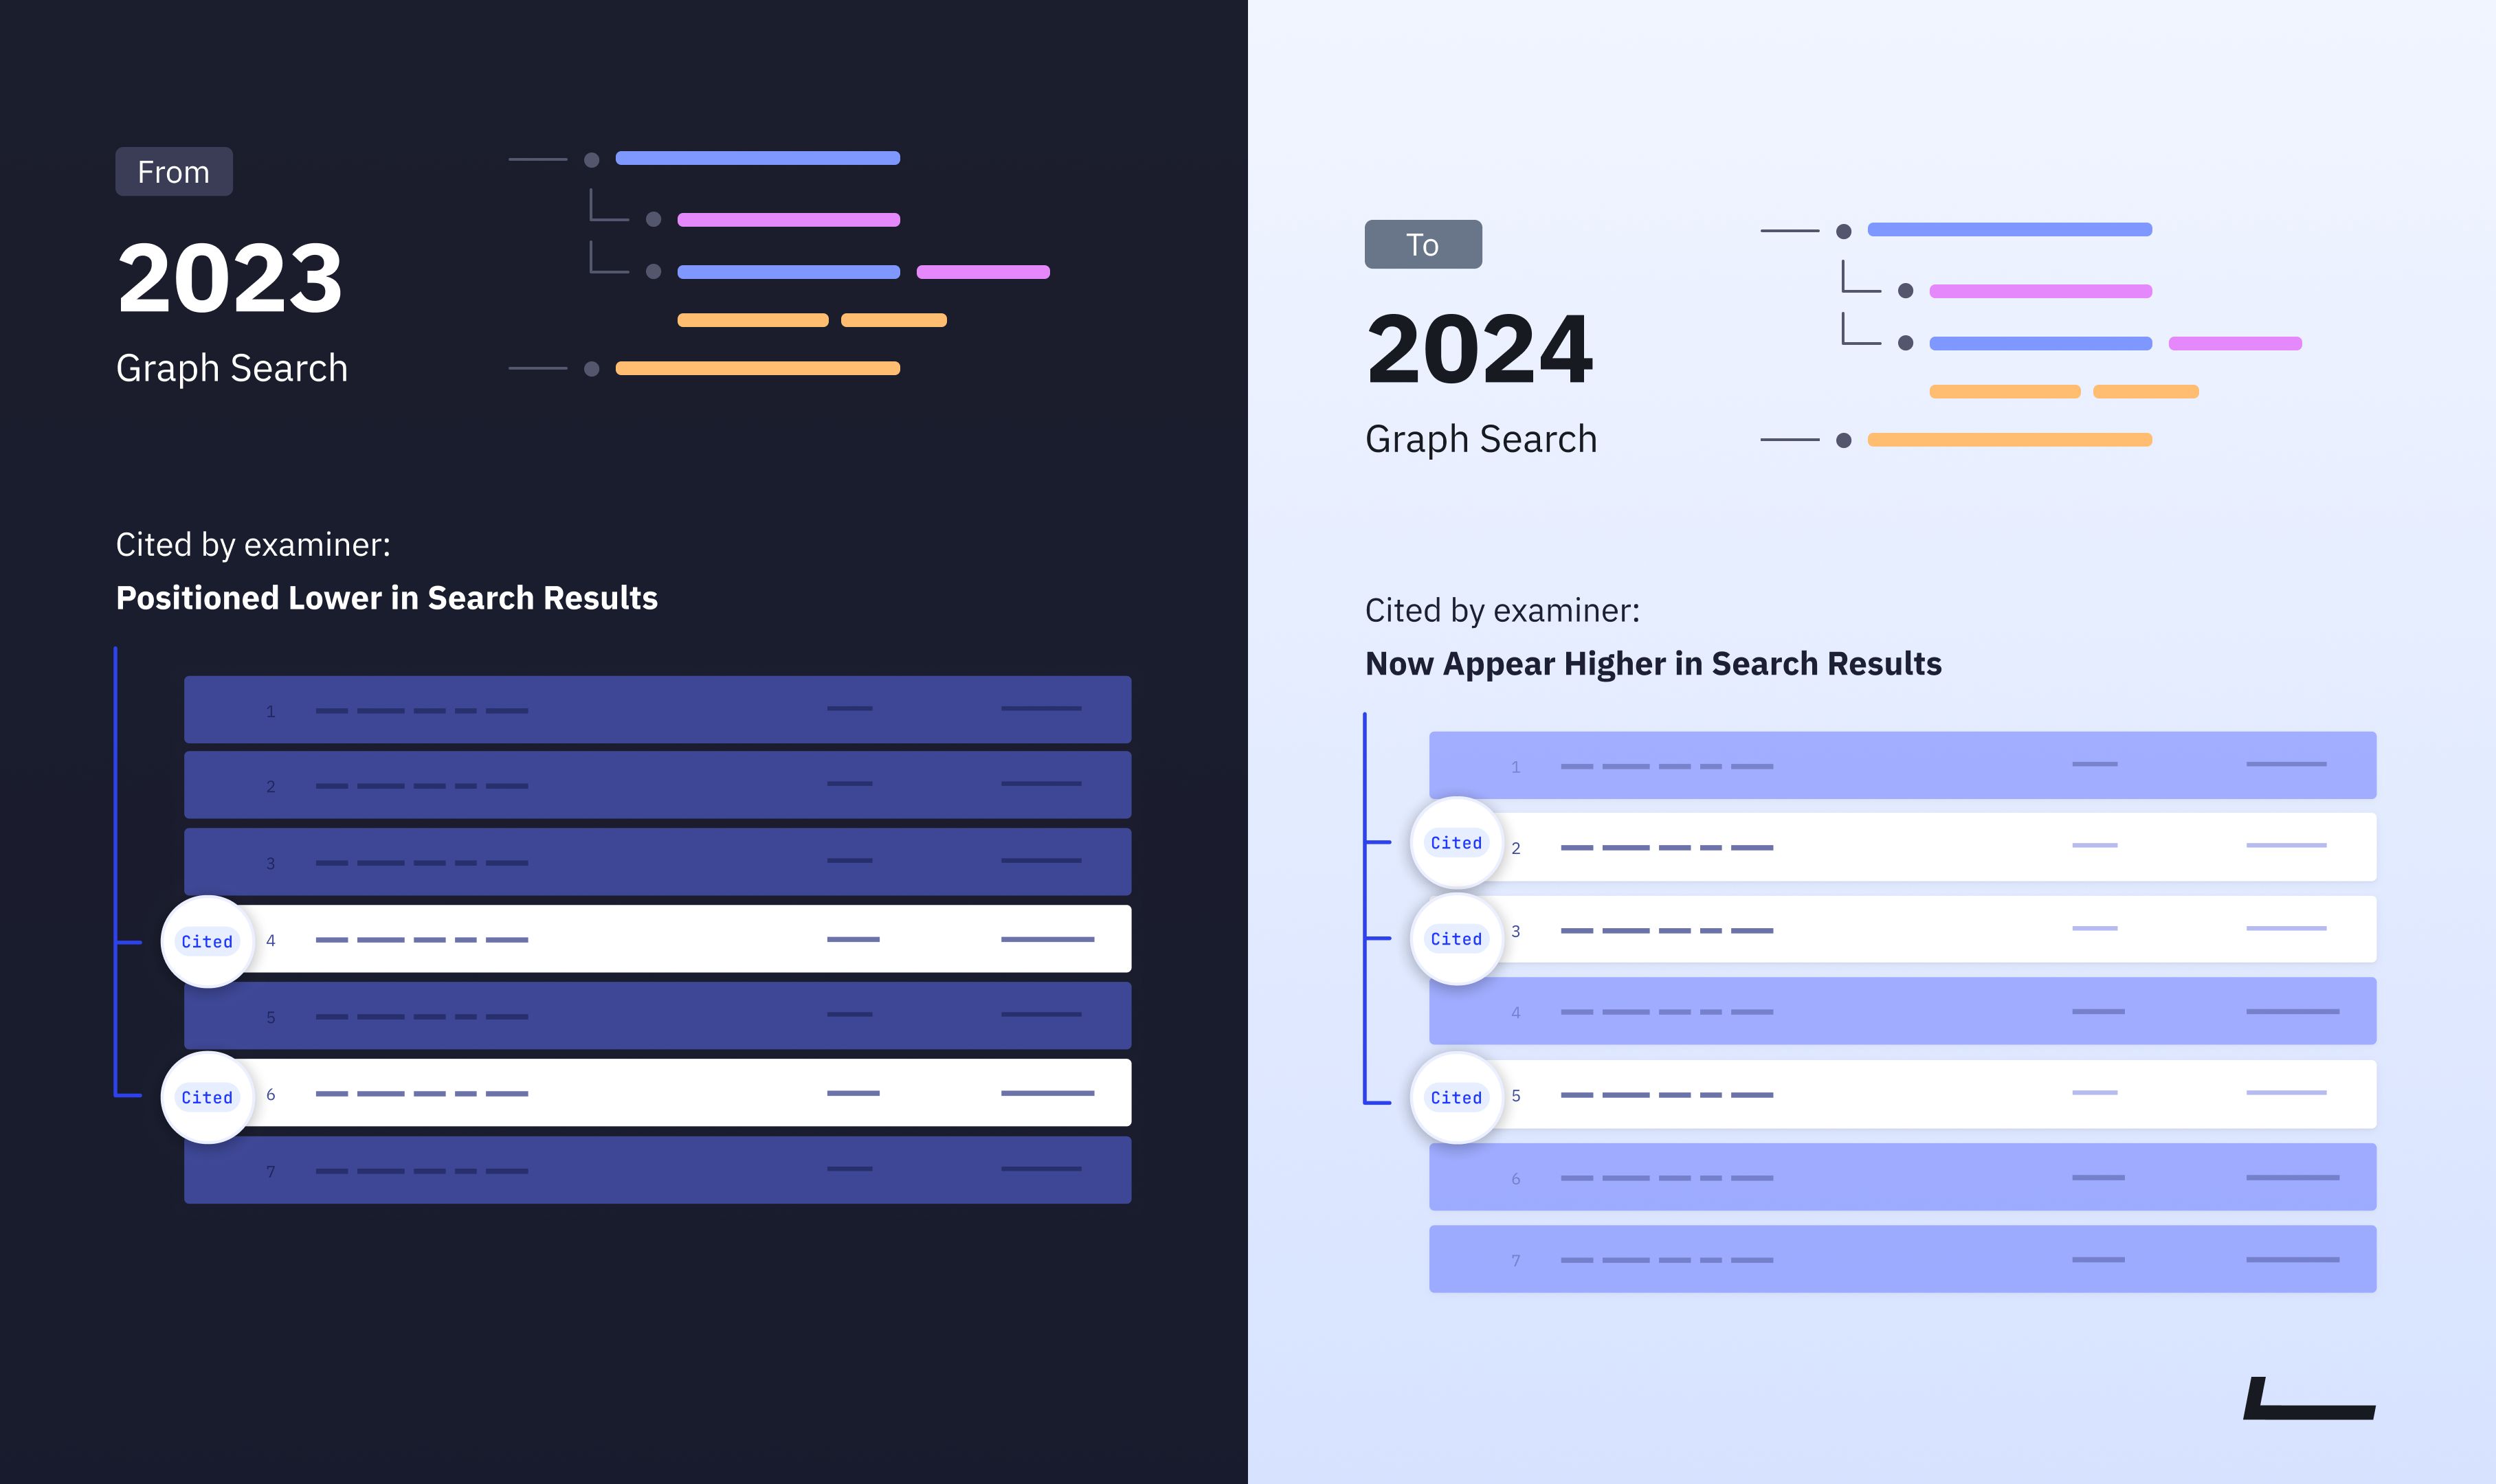
A year ago, you needed to read twice as many documents for the same confidence as today. Recall has improved to the point where today’s recall at 10 documents matches what it was at 20 documents a year ago. Eventually, with this pace of development, Boolean searches must become obsolete. Boolean is essentially a filtering method, and as the AI search improves, such filtering becomes increasingly redundant.
Can we sustain this pace? It appears that, at least for a while, we might – we have several improvements on the horizon. However, I wouldn’t yet call this new pace the "Moore’s Law" of patent search.
Why Graph AI and Not Generic AI
GenAI has shaken the world, leaving only a few to continue working on search engine technology with proprietary machine learning. GenAI is not a silver bullet for search though. It is still expensive and it is built to solve text generation, not retrieval. It might not be that helpful even for reranking i.e. sorting the top results. The underlying technology is undeniably powerful, however. We also benefit from these developments, as the transformer architecture powers our search.
In 2018, with just €150k in pre-seed funding, graphs gave us the chance to develop a scalable compromise-free patent search engine. Somehow, we succeeded. Today, the original advantages over generic search solutions still apply. We have three 10x levers that compound together:
- Supervised training with patent examiner citation data. Patent data might be the best dataset of them all for building an AI search engine.
- A magnitude more efficient training with the graphs that contain only 600 nodes, compared to the 10k tokens in a full text of a patent document.
- A magnitude more efficient attention mechanism through the graph structure, compared to the LLM-style global attention.
We are finally in a place where we're confident that our search tool is the best one out there. Yet, Graph AI is still imperfect. One of the biggest current challenges is that preprocessing documents into graphs leads to some loss in data quality. This is an area that is guaranteed to improve, especially considering advancements in natural language processing.
First the Bottlenecks, Then the Huge Leap
We are not optimizing for short-term gains but aiming to create the dominant search model for the mid-to-long term. For instance, we avoid using gigantic models. While the new model has approximately doubled the number of parameters to 200 million, this is still small in the grand scheme of things. Our strategy is to quickly reach a point where we eliminate obvious bottlenecks, and then take a leap to significantly scale the model.
We’ve maximized the speed of our RnD. The architecture is simple as we don’t even use a reranker. We have also maintained a tight focus on patents rather than adding new data sources. While we could have invested time in improving searches for specific fields like chemistry or computer science, we've chosen to prioritize our focus and development speed.
In addition to the tight focus, we have accelerated RnD by investing in getting the infrastructure and MLOps right. Today, we have one of the most cost-efficient cloud-based deep learning training solutions out there. I had the opportunity to present our ML platform at Google Cloud in Las Vegas in April. Here is an article about it.
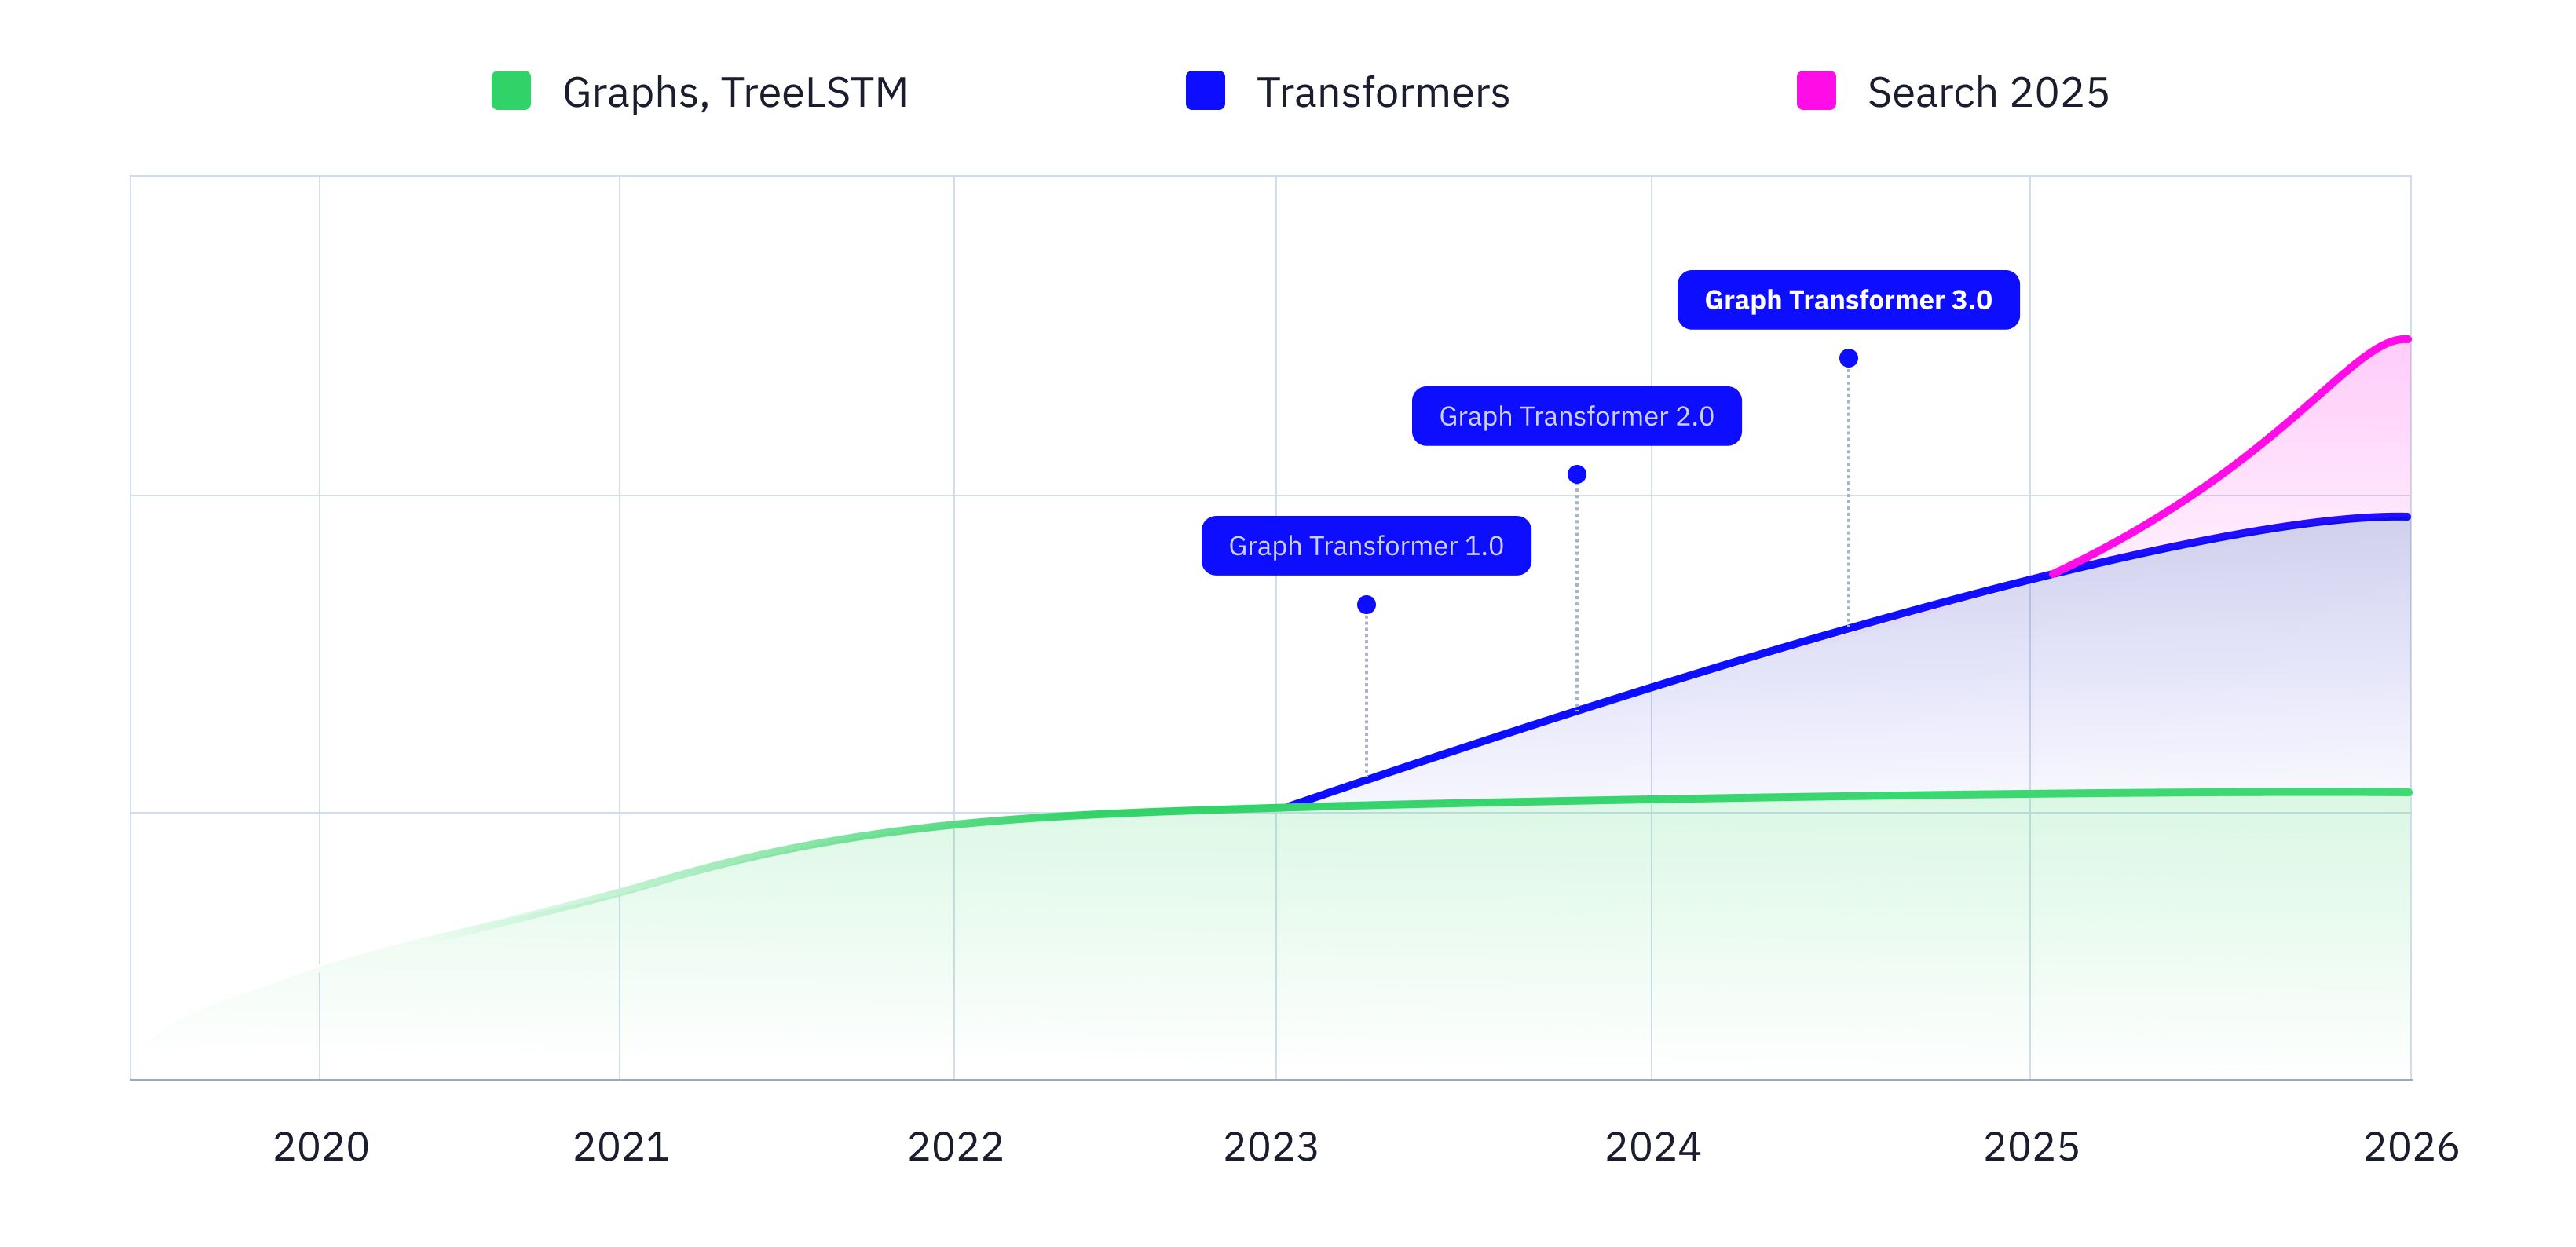
Search technology is advancing rapidly with insights from GenAI. Our goal is to achieve a lasting edge in the patent search space with Graph AI. I wouldn’t teach my son to write boolean queries for patent searching.
Meet Juho In the Latest Episode of the RallyCast
In this episode, John Paul Keeler invites co-founders Juho Kallio and Juuso Piskonen to talk about the history and future of IPRally, how it all started, the difference between Graph AI and LLM, and why the snow thrower became IPRally’s mascot. Watch it here.