The world’s fastest Tree-LSTM

Our story about utilising neural nets with tree like data. Can a Tree-LSTM model be used for real world applications? Turns out the answer is yes, but only after the performance is improved by 7000%.

Last summer we started looking for deep learning solutions for tree shaped data. Tree-LSTM* seemed to be the simple and proven model we could use as the core of our patent search. There exists lots of working implementations, and though they all are for slightly different problems, it was no big trouble to convert one to work for us. In August we had a model that clearly was learning something. All was good, except it wasn’t. The training speed was horribly slow, ~20 iterations per second, and our data was in millions of training samples. The model managed to utilise mostly just a single CPU core, and training with GPU was even slower than that. Further research gave a grim picture. The naive implementation of the model handles only a single sample at time, when usually you want to be able to process 10-1000 samples in parallel. To make matters worse, the model also processed all the tree nodes separately.

‍

The main source of speed in machine learning comes from parallelism, which is achieved by computing similar operations in big batches. This has three benefits. First, it allows utilising GPUs which can have over 1000 cores and with neural networks can give 50x speed benefits over CPU. Second, the matrix multiplication that is the heart of most models, is actually cheaper when you can have one big operation instead of many smaller ones. Third, the code needs to be parallel so that we can scale the speed with money. The vanilla Tree-LSTM is basically unusable even with a supercomputer, as it wouldn’t be able to utilise much more than a single CPU core in the training phase. Making the model work in a parallel fashion was needed, but everyone seemed to view it as a very difficult challenge:

“This type of model, i.e. a recursive neural network, will have a different structure for each input sample, and it is extremely difficult (almost impossible) to find samples which might result in almost similar structures, so that we can batch them together.” Github issue about Tree-LSTM performance
“Neural models operating directly on parse trees are usually difficult to parallelise and thus computationally inefficient, because aligning trees for efficient batch training is usually nontrivial.” Zhang et al., 2018
‍

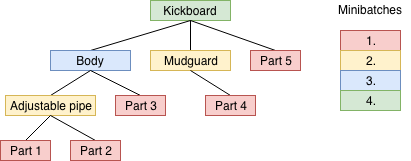
‍The tree is processed starting from the leafs, i.e. the details of the invention. This way we can also process many trees simultaneously.

We could have tried different models, but Tree-LSTM seemed to work, and there was something that didn’t make sense. We know what we need to calculate and we can do that in parallel - what exactly is stopping us from doing just that? First we can calculate the nodes that only have edges to the leafs, after that only the nodes that have all the data available, and so on. For sure, there are few reasons why this is not trivial. The index calculations are mind bending by nature, and the simplest implementations seemed to mess the backward step performance where the learning of the neural net happens. Luckily we were living in 2018 and had chosen PyTorch, which provides some wonderful indexing functions. When you manage to use these functions for the heavy parts, the code is pretty much automatically efficient.

‍

So, is this the fastest Tree-LSTM in the world? Not necessarily, as we recently found out that someone brilliant had done something similar with the old TensorFlow. According to the readme, nicolaspi’s implementation is 70x faster than vanilla Tree-LSTM, which is similar performance gain as what we have measured. Someone could have improved over that as well. Nevertheless, we have room for improvements, e.g. we can calculate the indexes in CPU at the same time the batch is processed by the GPU. The end result will be a Tree-LSTM model that is fast and scalable enough to be used with any kind of data, and can utilise GPUs fully. The similar optimisation strategies have also proven handy with other models, which is another story.

‍

*) If you are not familiar with Tree-LSTM or recursive neural networks in general yet, Stanford lecture in Youtube is a good watch.
Read more

Webinar Q&A follow-up: your questions about the IPRally MCP answered

Thank you to everyone who joined Patent answers, inside the AI you already use. Across the two sessions on 4 November, you sent us more questions than we had time to answer live. We have grouped them by theme below, merged similar questions and included the answers given during the sessions.

Your IPRally workspace, wherever you work

Your AI assistant can now pick up where your IPRally work left off. The IPRally MCP now reads your collections, tags, search cases, projects, and agent runs, so your agent starts from results you’ve already vetted instead of a blank prompt.

Webinar Q&A follow-up: your questions about IPRally Drafting answered

Thank you to everyone who joined No more drafting in the dark: prior-art-aware patent drafting with IPRally Protection. Across our EU and US sessions, you sent us more than 80 questions, from file formats and drawings to claim clarity and US disclosure duties. We have grouped the answers by theme and merged similar questions. Some were answered live or in the chat during the sessions, and we include those here too.

Webinar Q&A follow-up: your questions about IPRally Intelligence answered

Your questions on IPRally Intelligence, answered: from working with larger datasets to verifying results at paragraph level.

IPRally is SOC 2 Type II compliant

IPRally has completed its SOC 2 Type II examination. Advantage Partners, our independent auditor, tested our security controls in operation from March 4 to June 4, 2026, and issued an unqualified opinion: no exceptions noted on any control tested.

When systems start talking: IPRally's journey toward a virtual IP department

Something new is happening: people talk to systems in plain language, systems talk back, and systems have started talking to each other the same way. As AI climbs from the small decisions to the large ones, the question for IP work is no longer whether it gets automated, but how to stay in control once it is. Co-founder and CPO, Sakari Arvela, lays out where this leads – through IPRally's new API and upcoming MCP support toward a virtual IP department that's always on – and why humans end up more important in that picture, not less.

Search, Intelligence, Protection: the three pillars of IPRally’s next chapter

For nearly a decade IPRally has been obsessed with getting one task right: patent search. Having built the best patent search in the world, we’re now reorganizing around three pillars – Search, Intelligence, and Protection – the newest of which makes drafting prior-art-aware from the first sentence. Co-founder and CPO Sakari Arvela maps out the next chapter, and why Protection is the shift he's most personally invested in.

NGen selects IPRally to bring AI-native patent intelligence to Canada's advanced manufacturers

After evaluating a range of tools on functionality, usability, and cost, Canada's Global Innovation Cluster for Advanced Manufacturing chose IPRally to power its Patent Search Adoption Tool Pilot Program.

IPRally and RPX Corporation announce strategic collaboration, cross-linking AI-powered patent search with RPX Empower

IPRally today announces a strategic collaboration with RPX Corporation, the global patent risk management service provider, that further expands the capabilities of the RPX Empower platform and provides seamless access to business critical complementary information for IPRally users.

Macro meets micro: IPRally's next chapter builds intelligence on search

Excellence in patent search was always the foundation. But foundations are meant to be built on. After years of staying focused – and saying no to a lot – IPRally is now ready to bring the same rigor and precision that redefined search to the bigger, strategic questions that businesses make decisions on. CCO Andreas Cehlinder explains why now, and what comes next.